SRE Intelligence | AI-Powered Site Reliability
Nife's AI SRE Intelligence engine (/sre/intelligence) autonomously monitors metrics, container logs, trace telemetry, and deployment events across your multi-cloud infrastructure. By applying machine learning anomaly detection models, the system predicts outages, isolates root causes, and surfaces automated remediation runbooks before end users experience degraded performance.
SRE Intelligence Dashboard
The intelligence dashboard provides real-time health grading, anomaly feeds, and proactive failure predictions across active services and clusters.
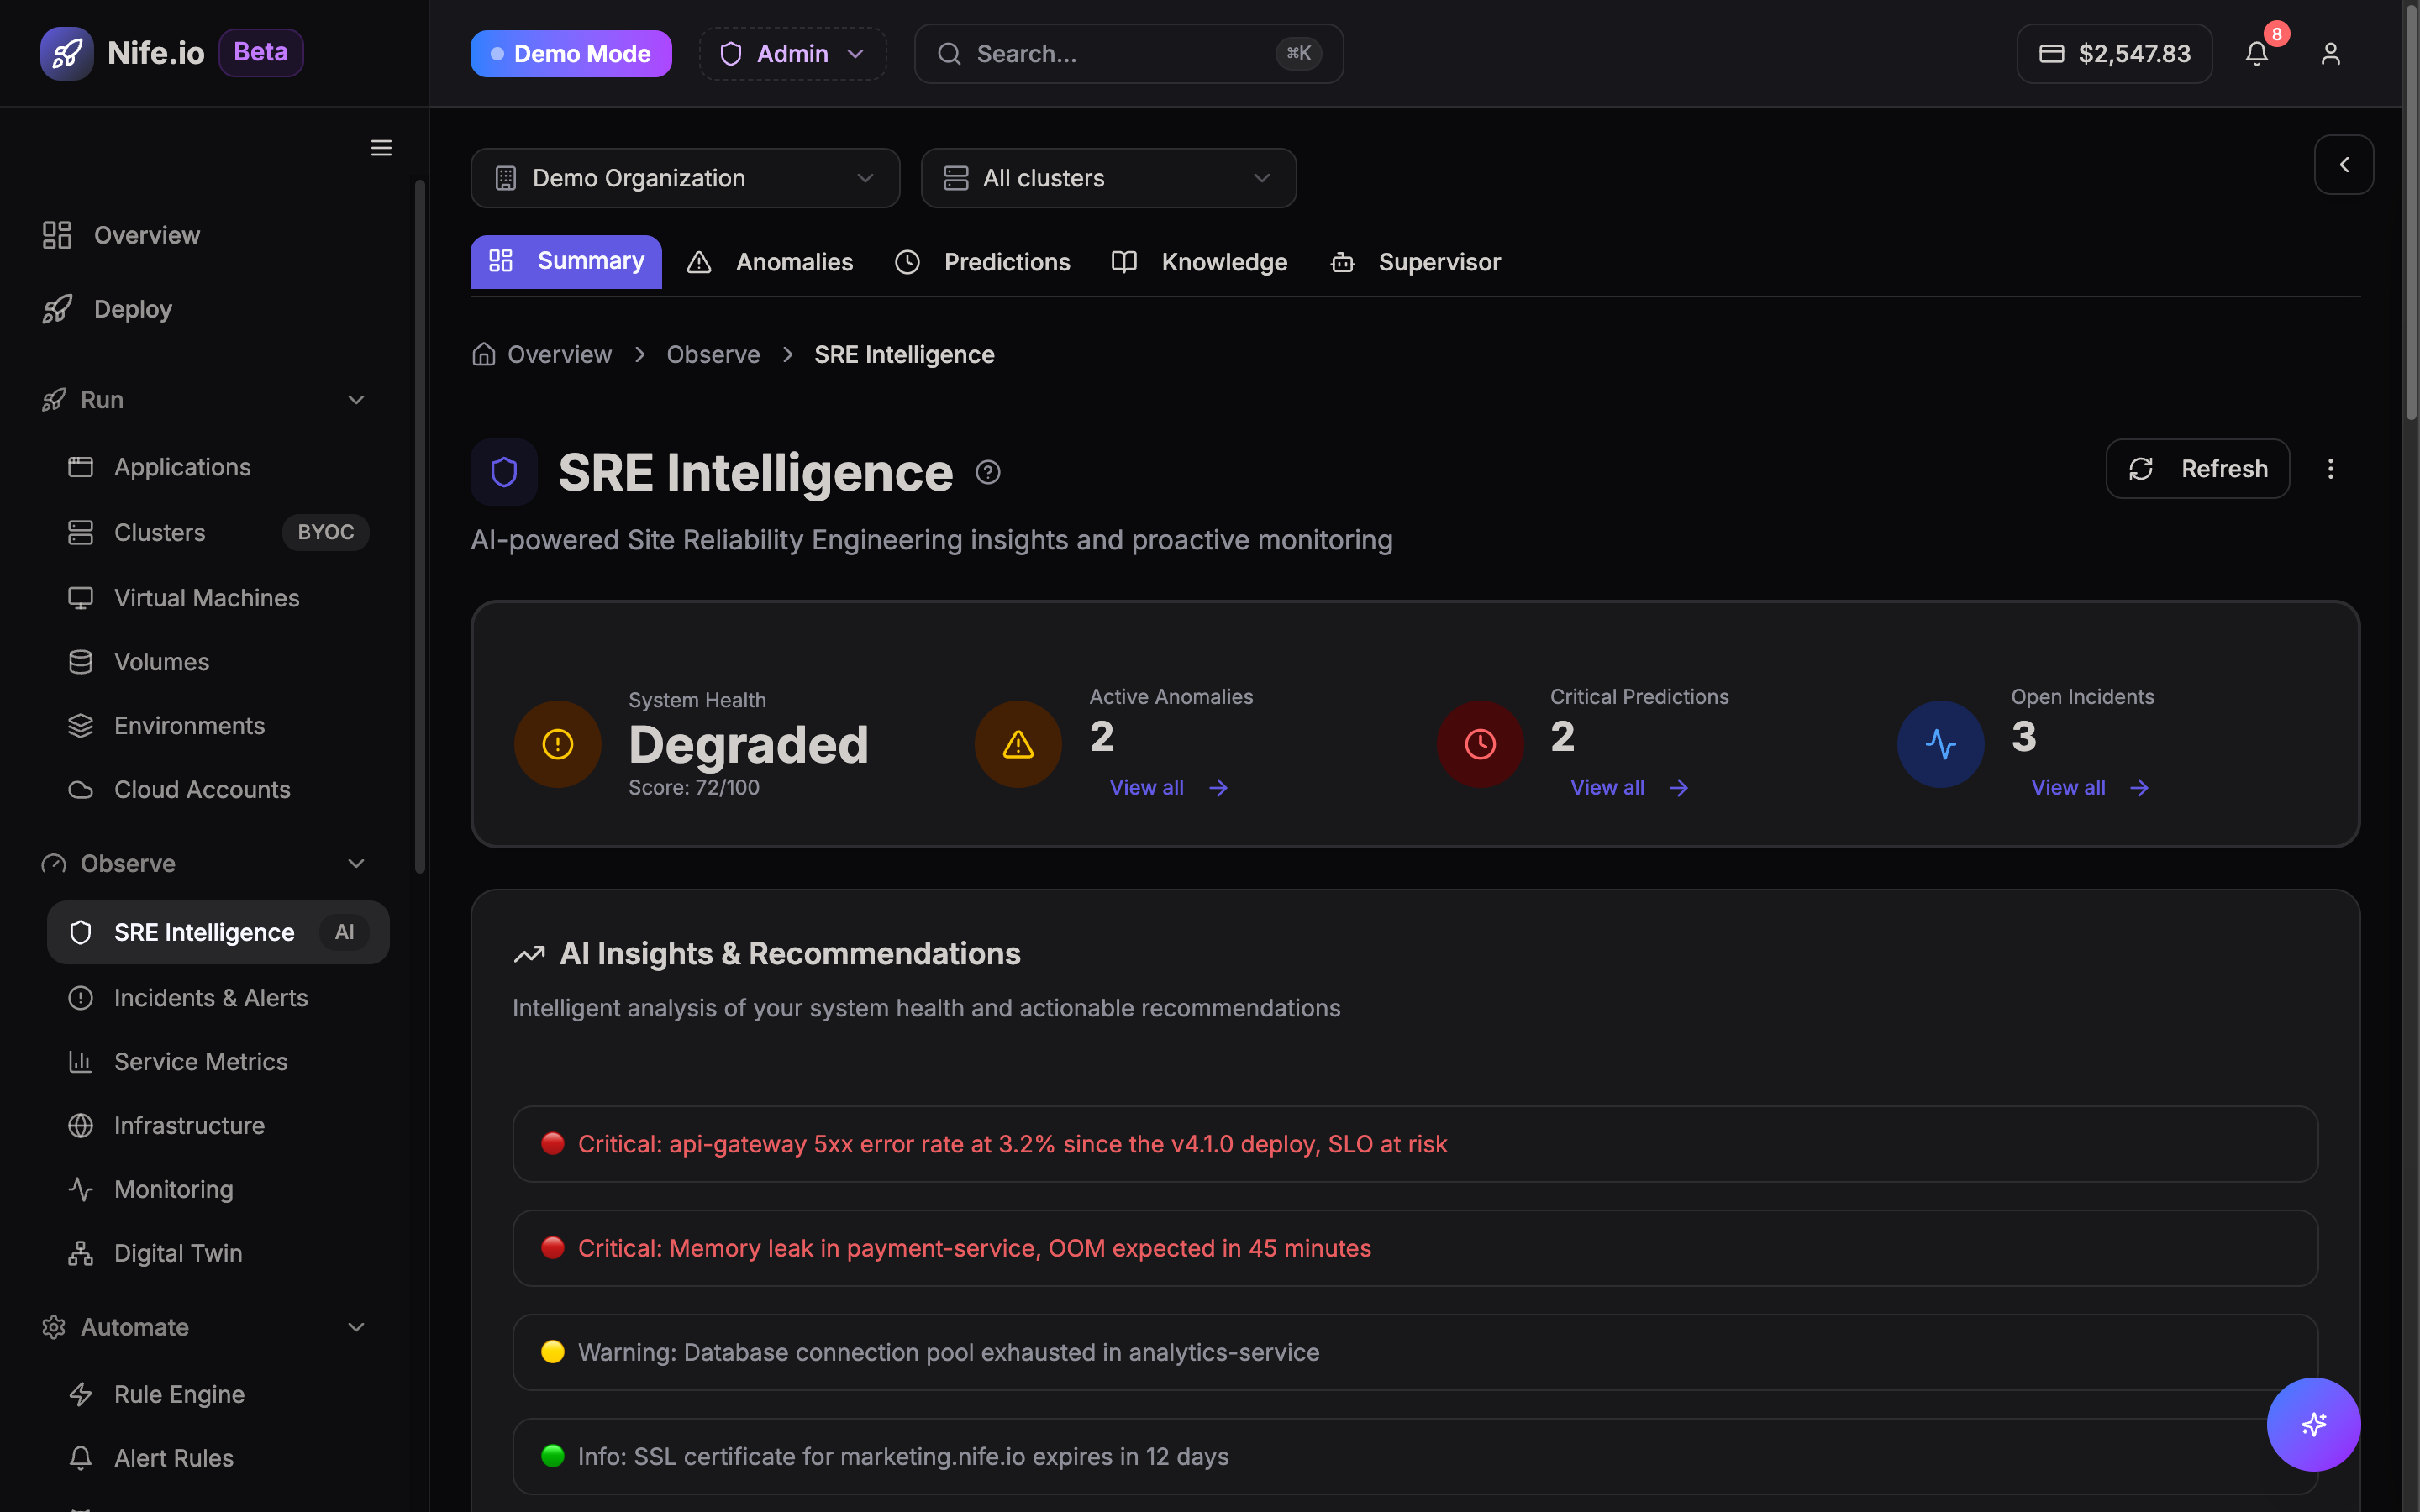
Core Capabilities
1. Automated Anomaly Detection
- Dynamic Baselines: Automatically calculates moving average baselines for HTTP response latency (p50, p95, p99), error rates (4xx, 5xx), and CPU/memory pressure without requiring static threshold configuration.
- Noise Reduction: Correlates transient spikes with background jobs or traffic surges, suppressing alert fatigue while surfacing genuine system degradation.
2. Failure Prediction & Pre-Emptive Mitigation
- Analyzes memory leak trajectories and disk I/O saturation to forecast container crashes or pod evictions hours before they occur.
- Suggests pre-emptive scaling adjustments or garbage collection restarts.
3. Automated Root Cause Analysis (RCA)
When an alert fires, SRE Intelligence correlates:
- Deployment Timelines: Flags whether an incident coincided with a recent Git commit, container rollout, or environment variable modification.
- Log Pattern Clustered Errors: Extracts unique stack trace signatures and fatal error logs across pods.
- Upstream / Downstream Telemetry: Pinpoints whether latency is originating in your application code or an external third-party dependency.
4. Interactive Remediation & Runbooks
- Offers one-click guided actions: Instant Rollback, Canary Divert, Horizontal Scale Out, or Pod Restart.
- Integrates directly with Incidents & Alerts and Webhooks to notify on-call engineers via Slack, PagerDuty, or Microsoft Teams.